Skip to content

I build production GenAI that isn't allowed to guess.

Alexis Roldan. Full-Stack Data Scientist & Sr. Data Engineer in Lancaster, CA.

Twenty years in biopharma manufacturing, thirteen of them in data roles.

I build manufacturing analytics and GenAI systems end to end — the ETL, the modeling, the app, the RAG layer, the deployment — on a global AI and data science team for Takeda's plasma manufacturing network, and I still own the Los Angeles site's two production platforms. The rule across all of them is the same: code computes the numbers, the model only explains them. Currently at Takeda Pharmaceutical.

alexis.m.roldan.ds@gmail.com

About

Who I am and how I work.

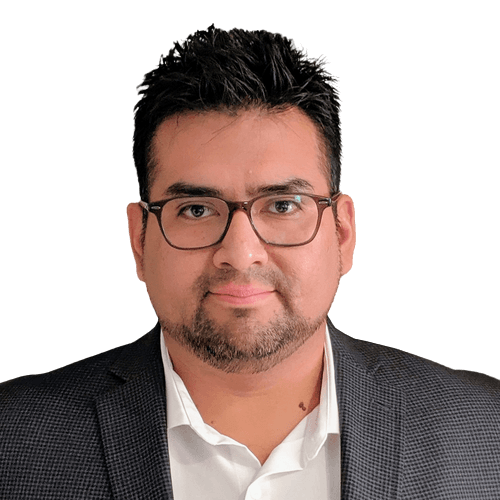
Portrait of Alexis Roldan

I turn biopharma manufacturing data into production systems.

I build production AI systems inside one of the most regulated manufacturing environments there is: human plasma fractionation. I started on the plant floor in 2005 as a manufacturing technician. Since August 2026 I work on a global AI and data science team for Takeda's plasma manufacturing network, and I still own the Los Angeles site's two production platforms — the ETL, the models, the apps, the RAG layer, the deployment and the executive deck.

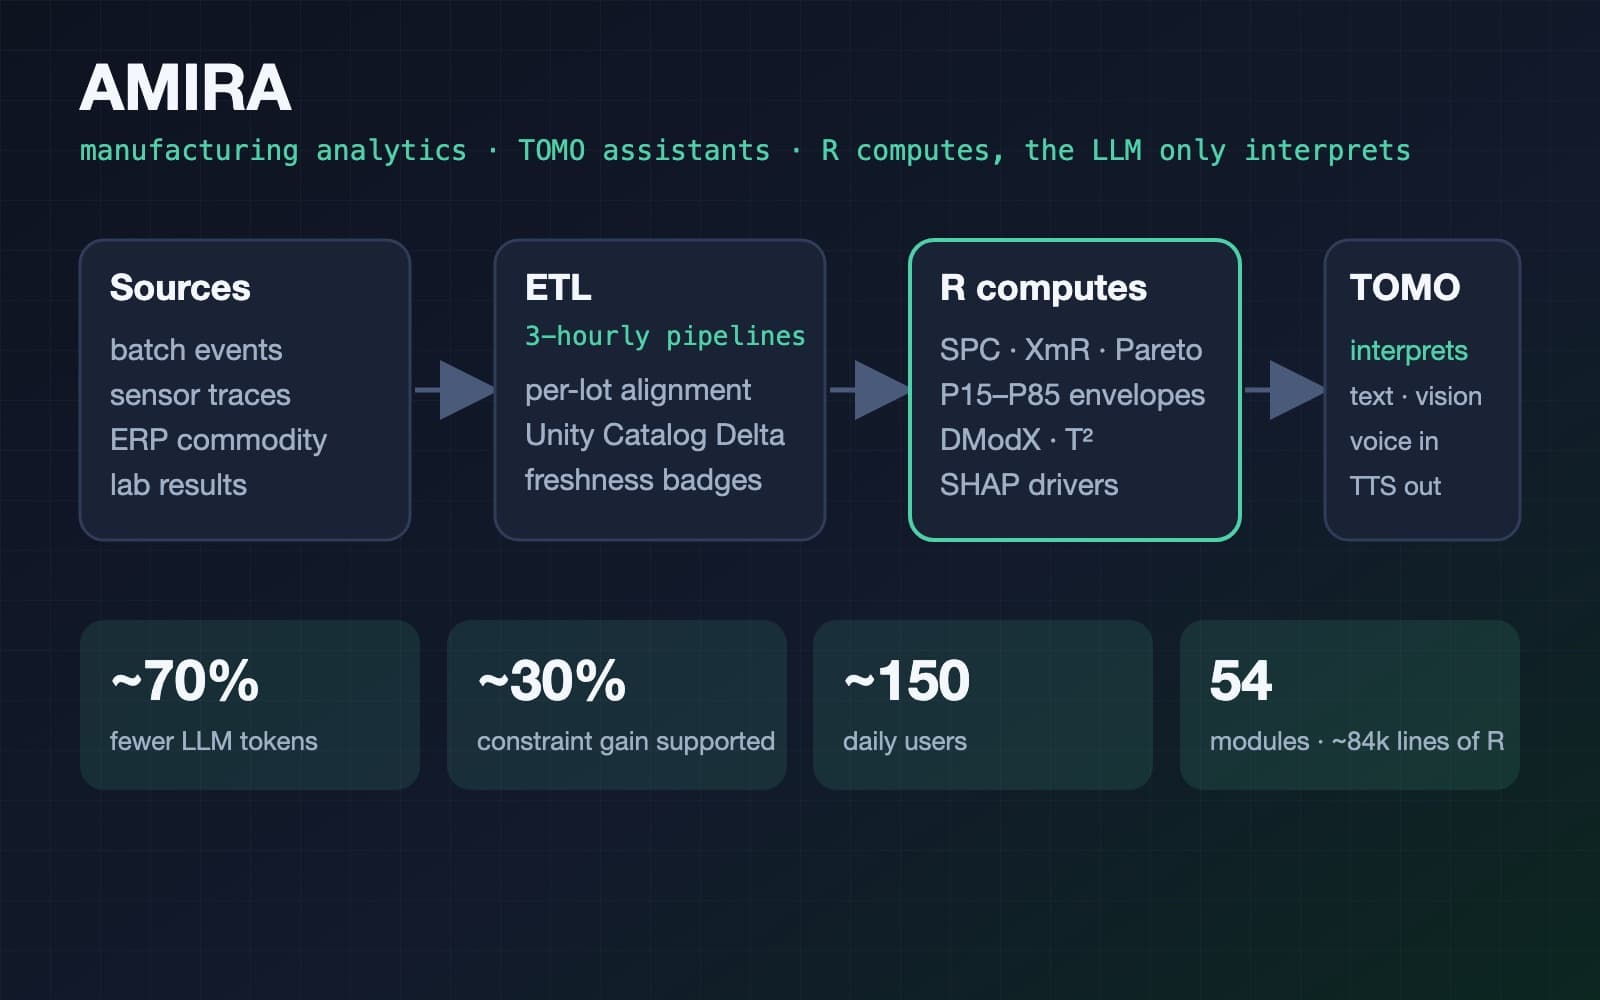
What I'm known for is a specific architectural position: deterministic code computes every number, and the language model is only allowed to narrate it. In a GxP environment a model that invents a result isn't a bug, it's a compliance event. The constraint also cut token cost by about 70% as a side effect.

The work I'm proudest of usually involves removing something. Recently I measured the base rate of a feature everyone wanted, found the signal present in three records out of five, and deleted it. A flag that fires on 60% of your data isn't a flag.

R, SQL, Databricks, TypeScript. Twenty years in biopharma, thirteen in data roles.

  • End-to-end data science and ML
  • Data engineering and pipelines
  • Business intelligence and visualization
  • Process optimization and digital twins
  • Generative AI and LLM applications
  • Lean Six Sigma Green Belt
  • AGILE Champion
  • Databricks Champion
  • Mulesoft Champion

English and Spanish (native), Japanese (conversational)

Years in biopharma
20

Plasma manufacturing, since 2005

Solutions shipped
30+

Apps, pipelines and models, 13 years in data roles

Daily users on the flagship app
~150

AMIRA, manufacturing analytics

Token reduction on LLM calls
70%

TOMO: statistics sent instead of rows

Recognition

  • Race4Value — FTE Optimization Winner

    2023, GMSGQ award across all plasma manufacturing sites

  • Star of the Quarter, Q3 FY22

    2022, Los Angeles site

  • Employee of the Quarter

    2017, Los Angeles site

Selected work

Production platforms in regulated manufacturing, and the personal tools I build to keep learning.

Filter projects by category:

20 projects, 10 with a full case study

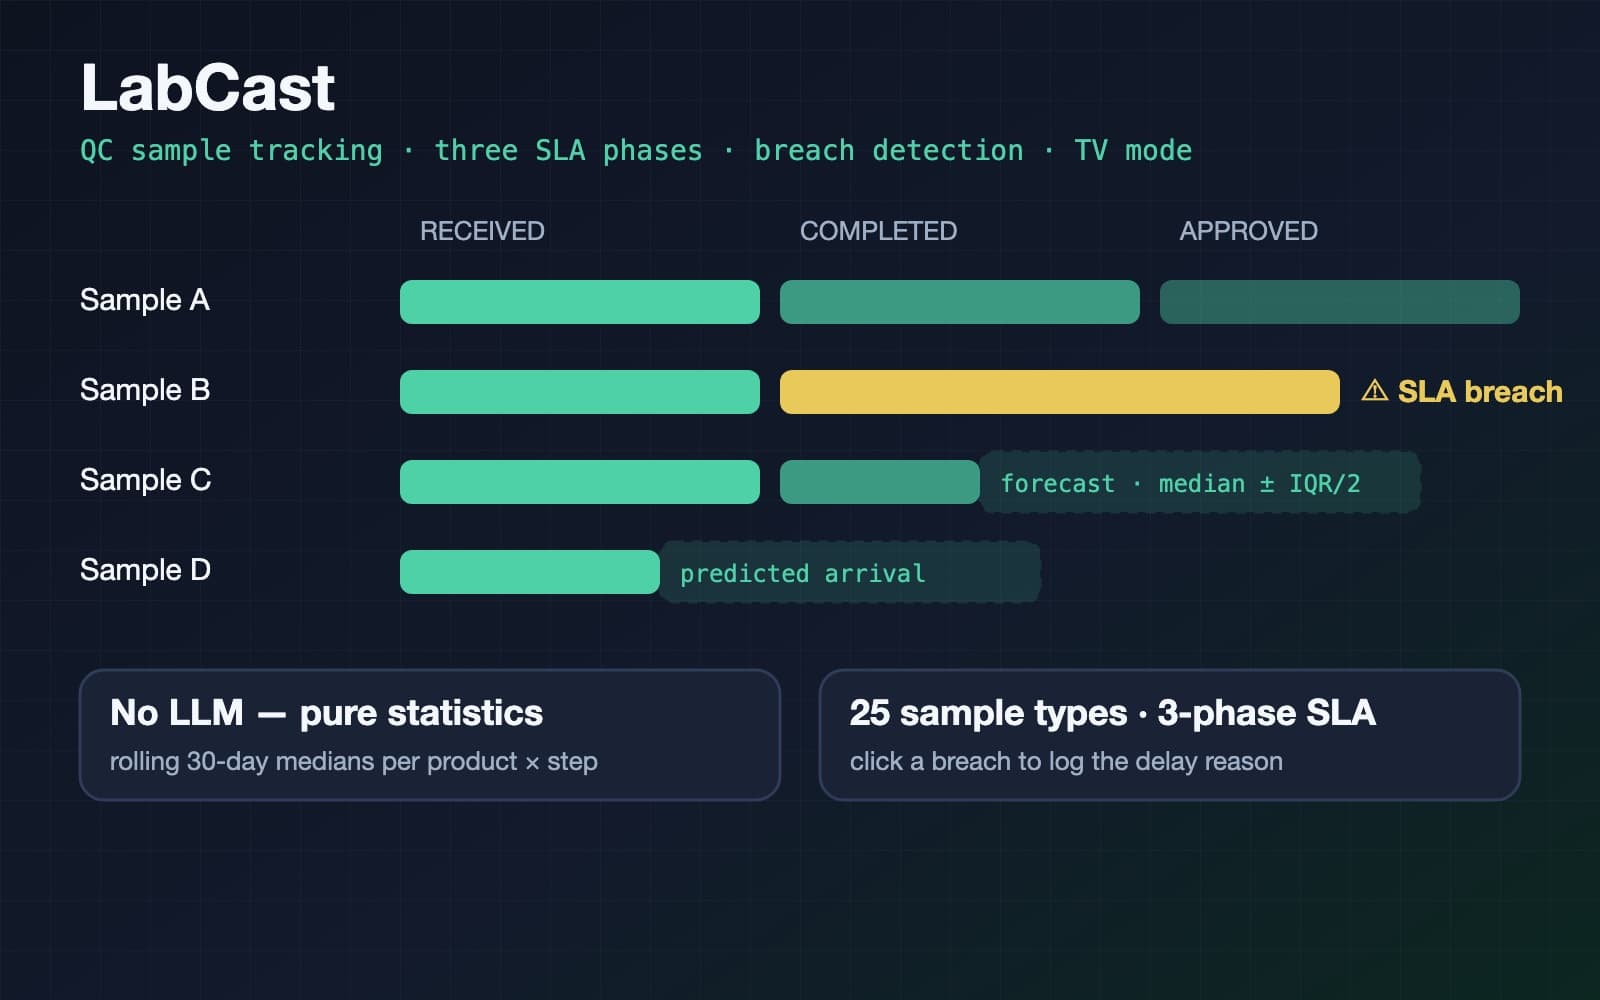
LabCast — sample lanes moving through received, completed and approved SLA phases with a breach flag and a median ± IQR/2 forecast band; no LLM, pure statistics

LabCast

Proof of concept

R / Shiny

QC lab sample tracking with TV/kiosk mode and a forecast model — 3-phase SLA logic across 25 sample types. A proof of concept on dummy data, built so users can see the interface working before deciding whether to move forward.

R Shinybs4DashForecast modelEDB / LIMS
Internal enterprise app
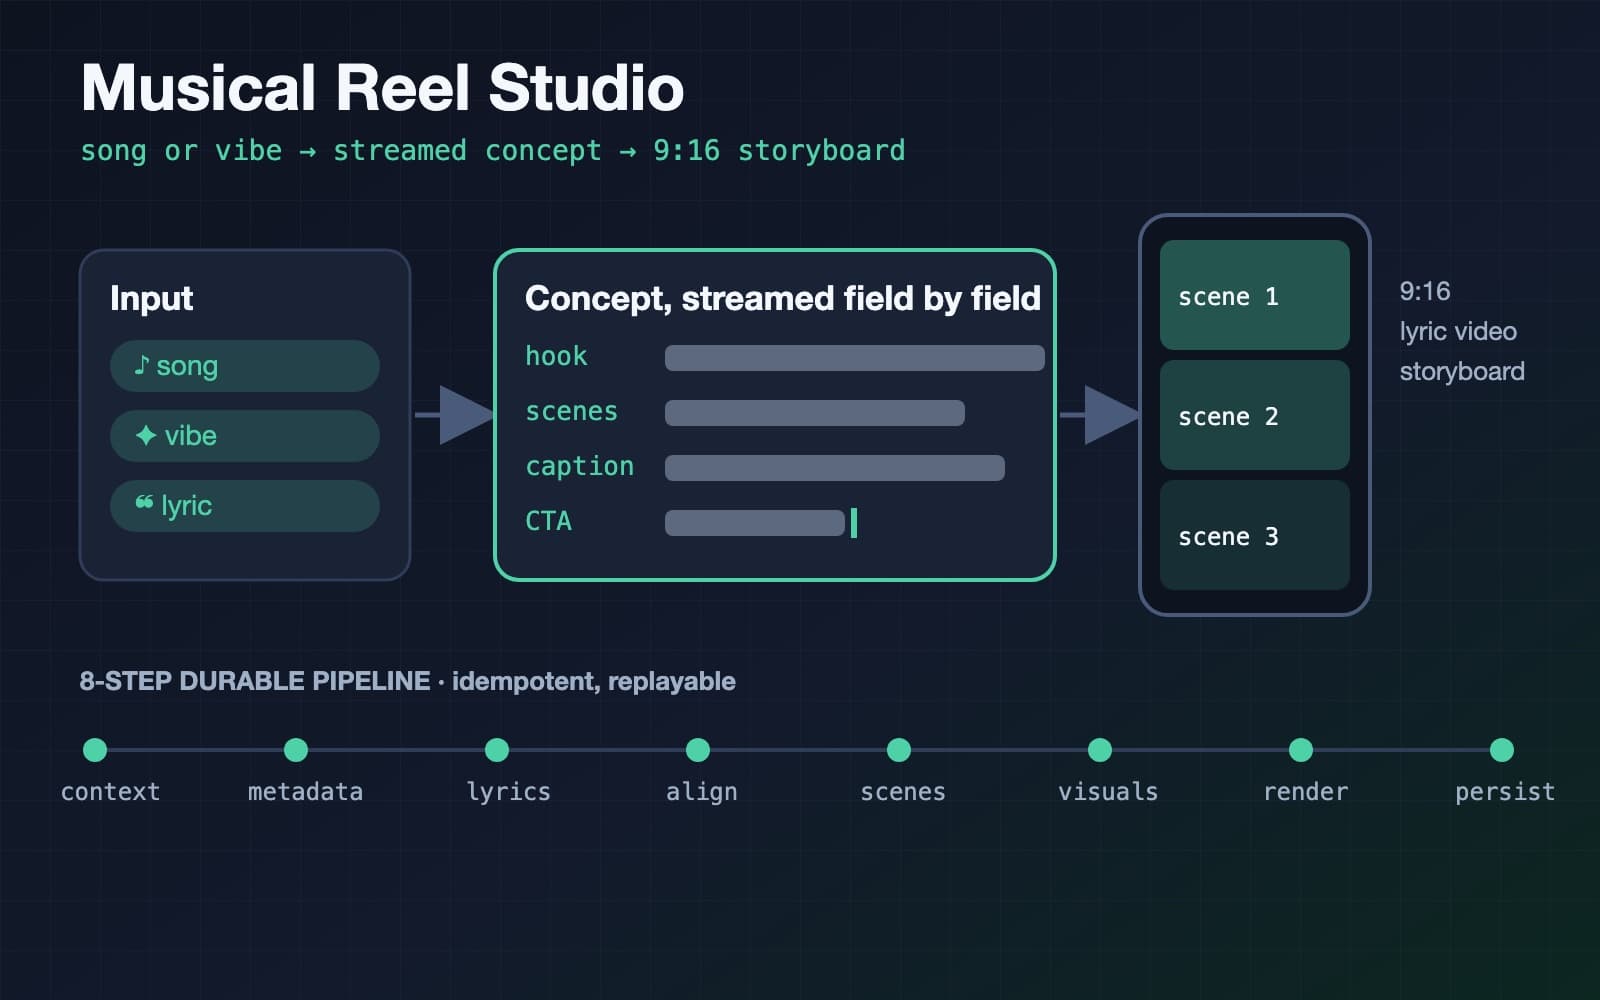
Musical Reel Studio — a song, vibe or lyric becomes a concept streamed field by field and a 9:16 storyboard, over an 8-step durable pipeline

Musical Reel Studio

Next.js / GenAI

Generates short-form reel concepts — hook → scene-by-scene → caption → CTA — streamed live, field-by-field from a song, vibe or lyric.

Next.js 15TypeScriptPrismaClerk
MVP, not currently deployed — walkthrough on request
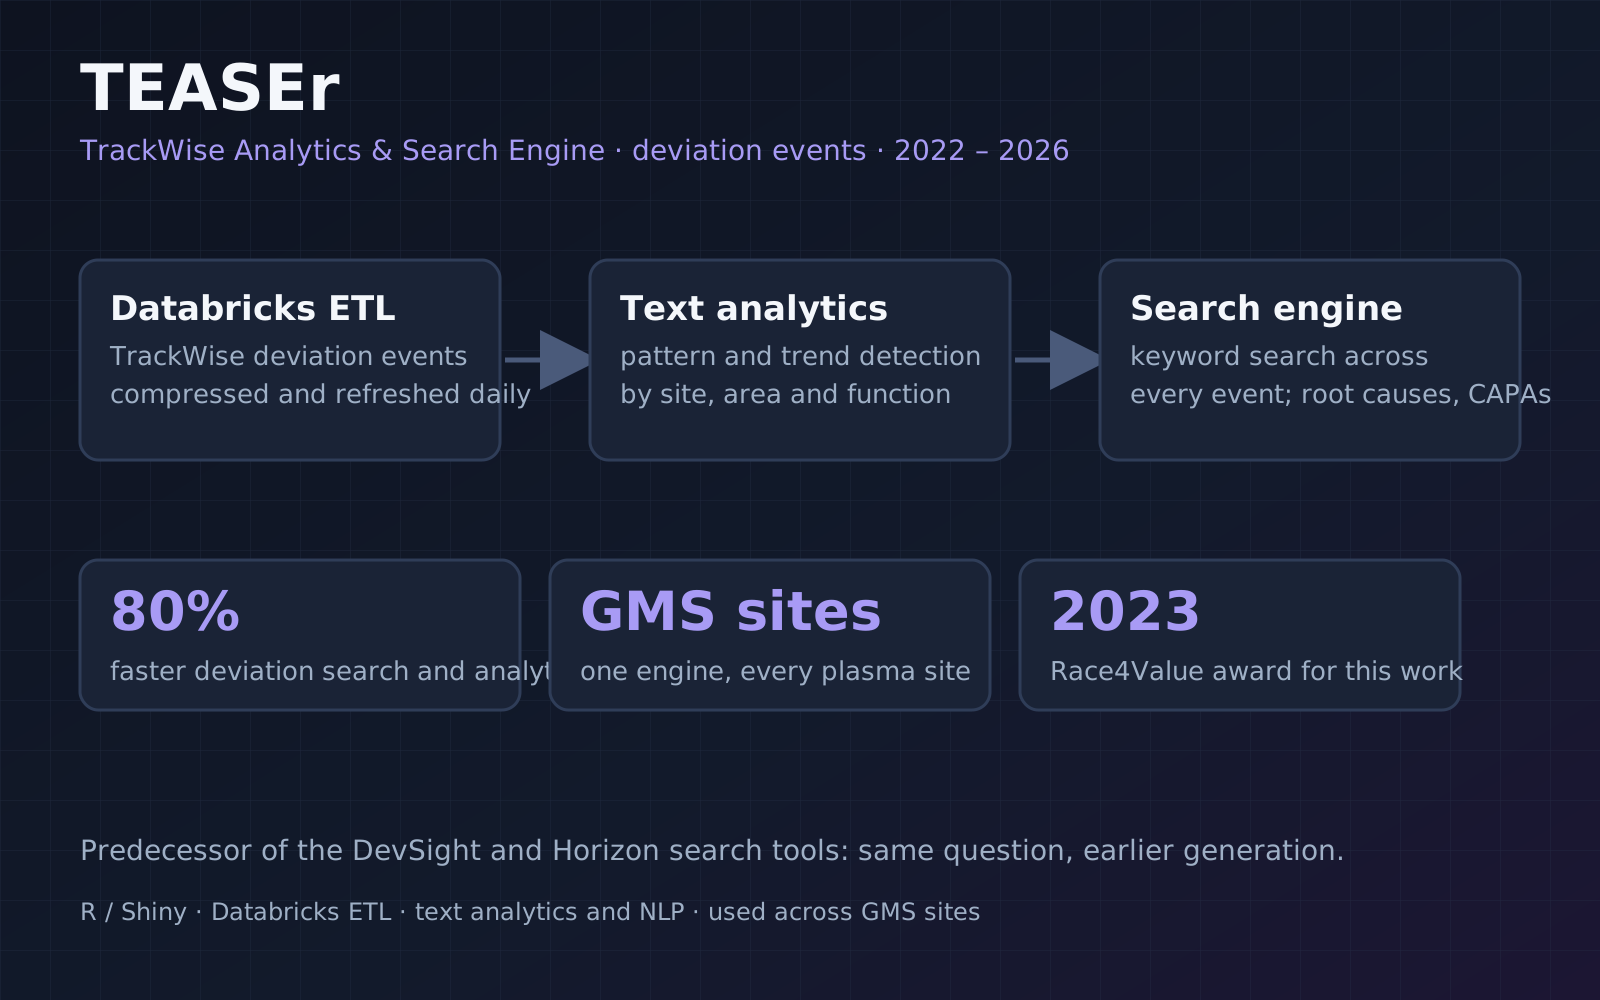
TEASEr — Databricks ETL feeding text analytics and a keyword search engine over TrackWise deviation events; 80% faster search and analytics, used across GMS sites, 2023 award

TEASEr — TrackWise Analytics & Search Engine

R / Shiny / NLP

R/Shiny text-analytics and search engine over TrackWise deviation events, fed daily from a Databricks pipeline: trending areas and functions by site, root-cause patterns with CAPA context, and keyword search across every event. 80% improvement in deviation search, closure and analytics, and the work behind the 2023 Race4Value award. Retired in 2026; the earlier generation of the question DevSight and Horizon later answered with retrieval.

R ShinyDatabricksText analytics / NLPQuarto ETL
Internal enterprise app
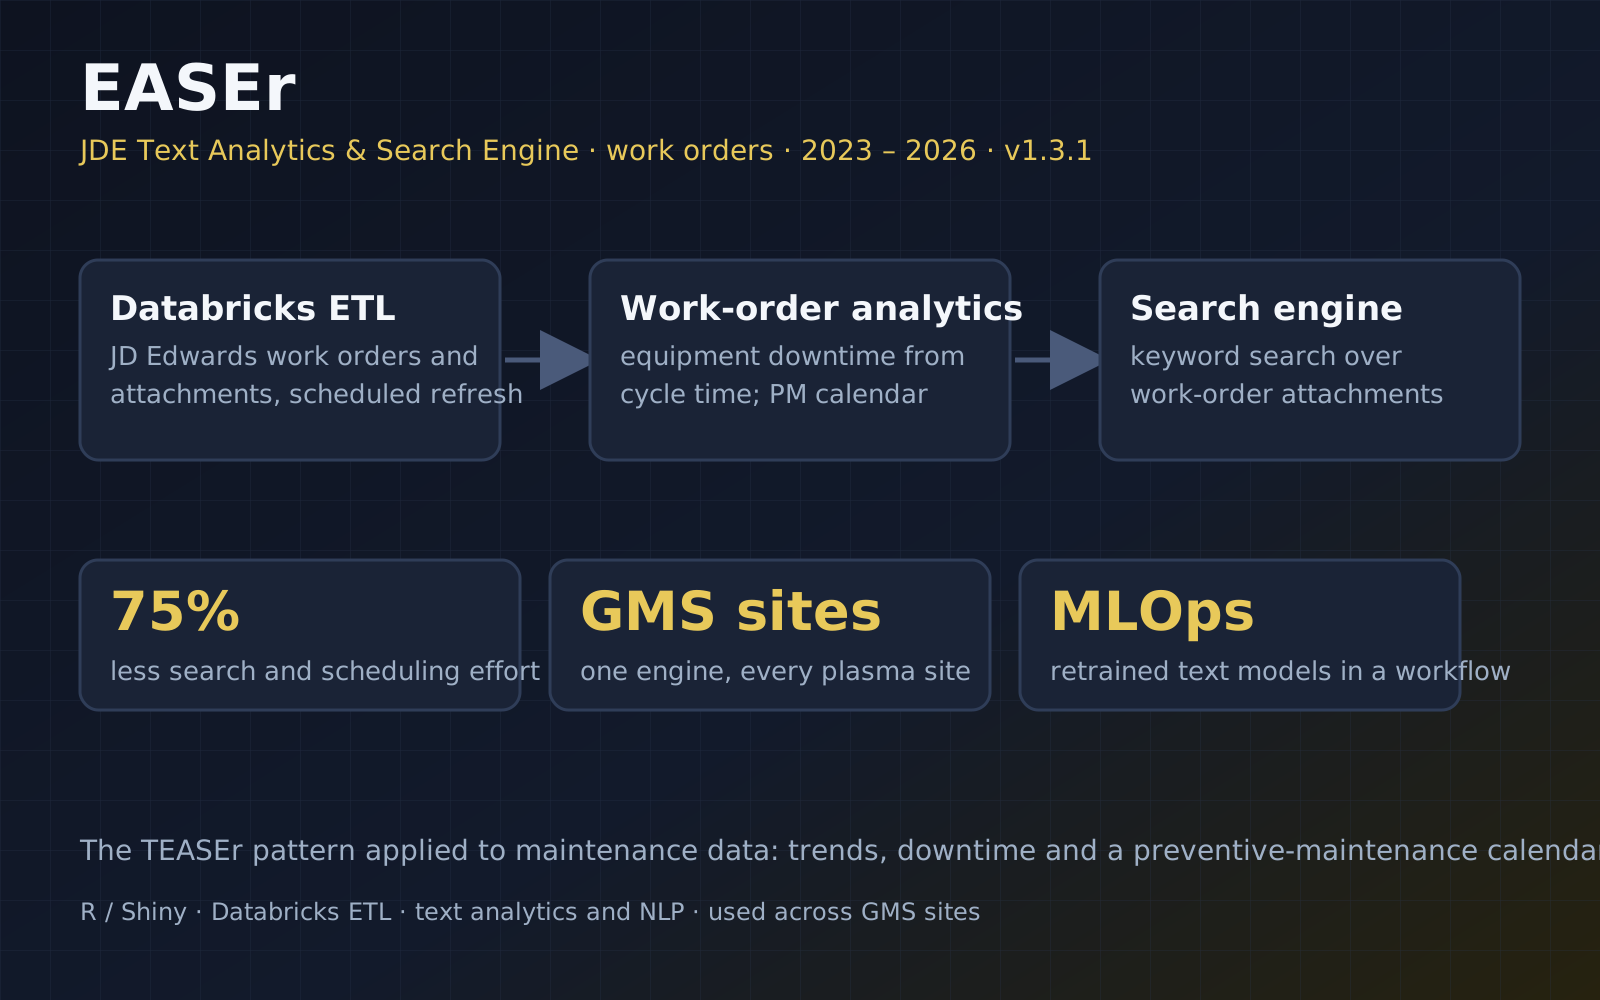
EASEr — Databricks ETL feeding work-order analytics and a keyword search engine over JD Edwards work orders; 75% less search effort, used across GMS sites

EASEr — JDE Text Analytics & Search Engine

R / Shiny / NLP

The TEASEr pattern applied to maintenance: JD Edwards work orders and their attachments wrangled in Databricks, then work-order analytics, equipment downtime from work-order cycle time, a preventive-maintenance calendar and keyword search over attachments, with text models retrained in an MLOps workflow. 75% less effort on work-order search, scheduling and trending. Retired in 2026.

R ShinyDatabricksText analytics / NLPMLOps
Internal enterprise app
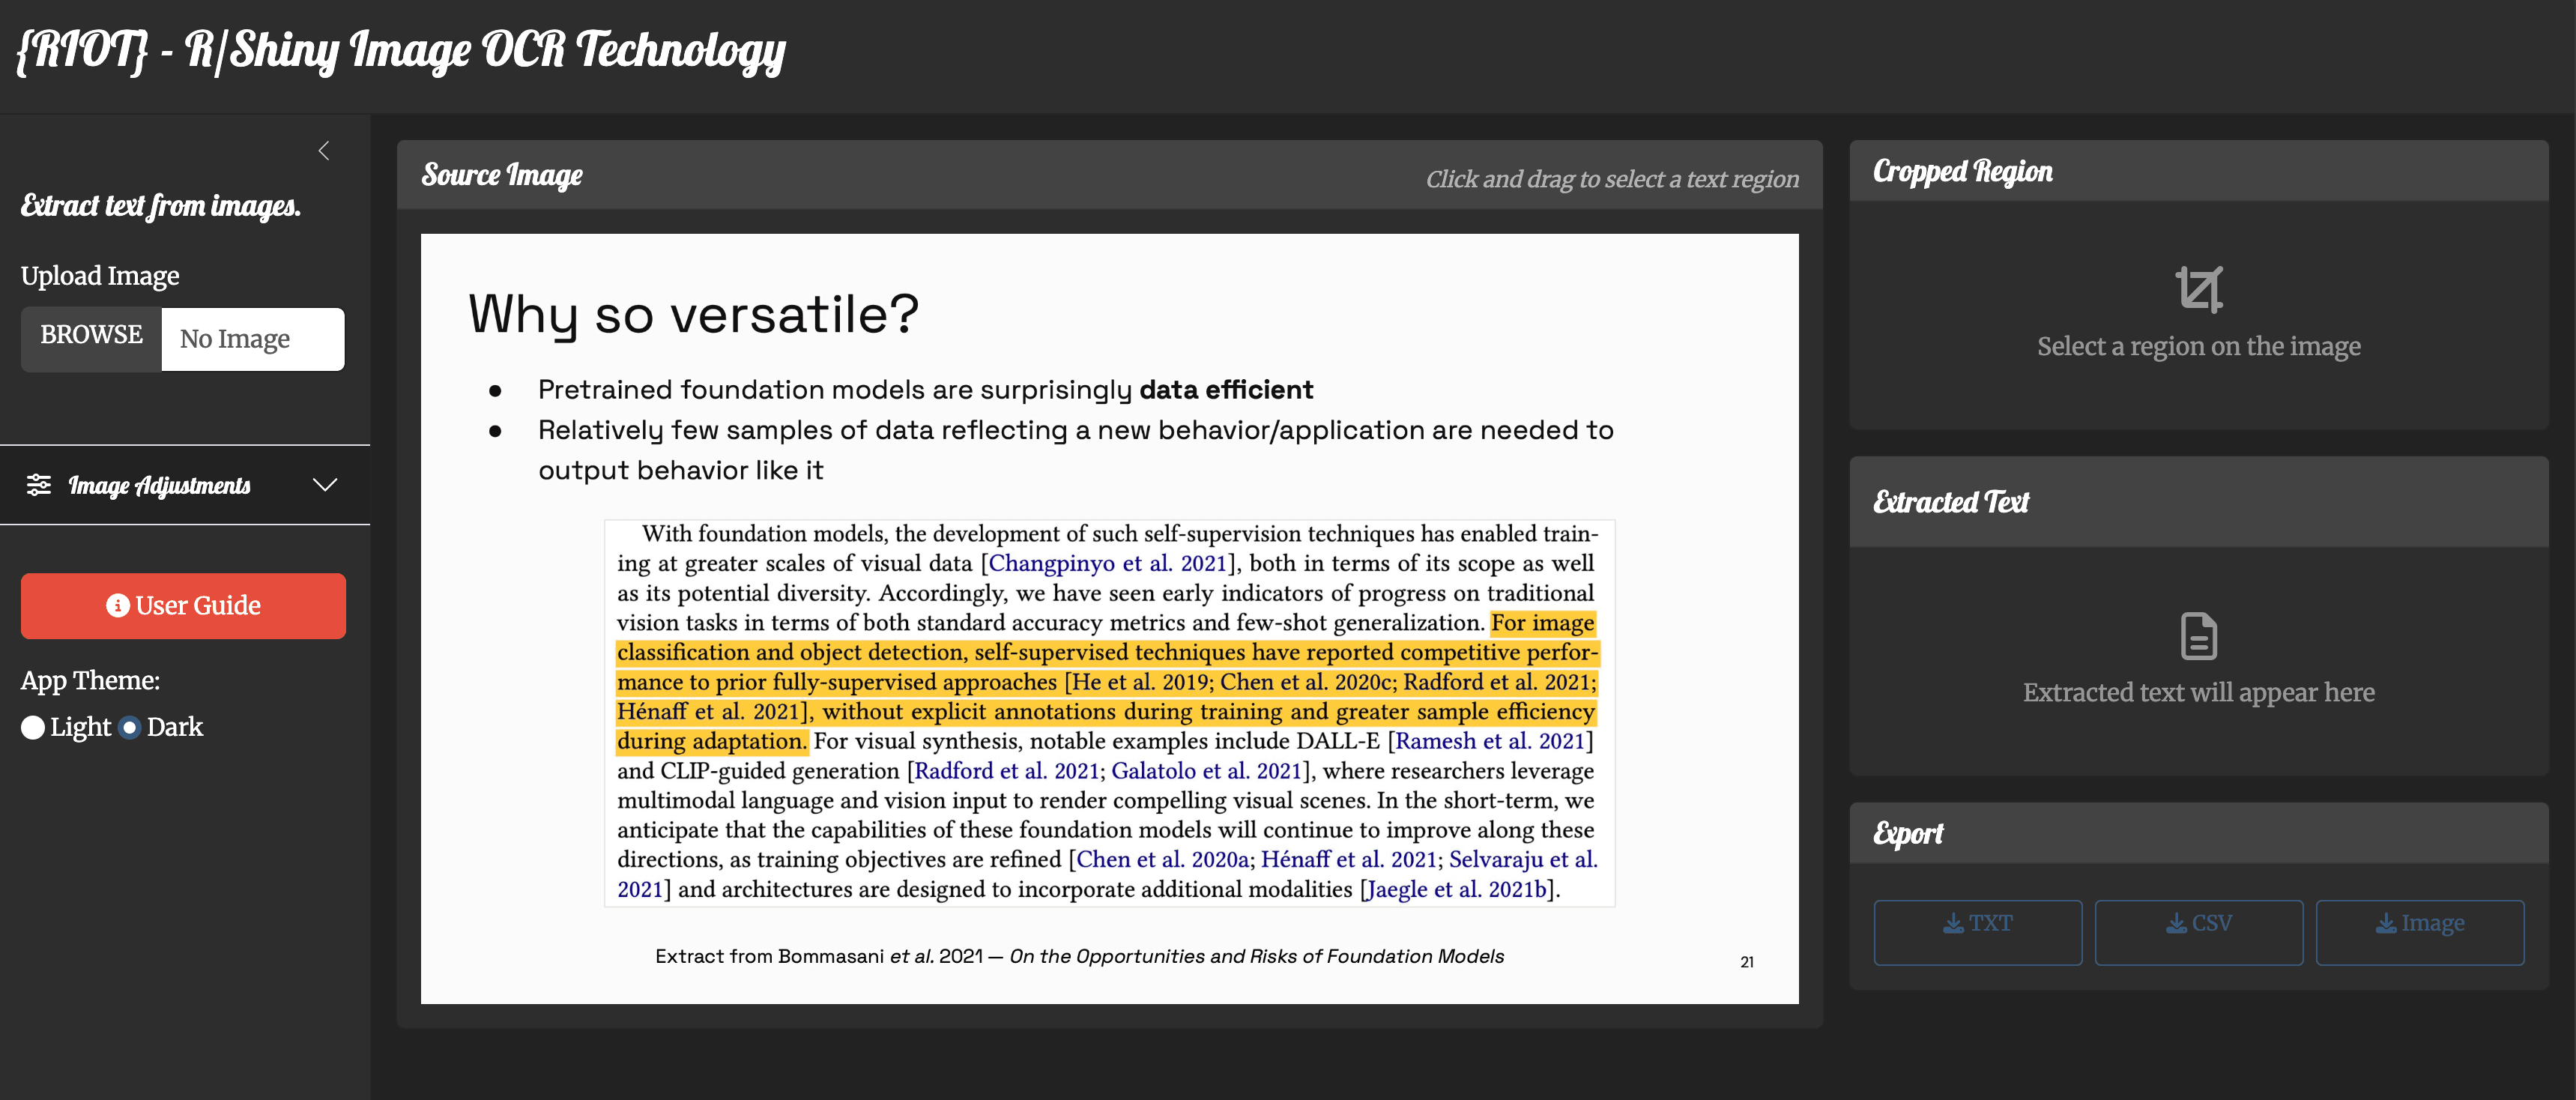
RIOT OCR application interface

RIOT — Image OCR App

R / Shiny / OCR

Interactive R/Shiny app extracting text from images with the Tesseract OCR engine — upload, select a region, extract for downstream analytics.

RShinyTesseractOCR
MultimodalText · voice · image · PDF

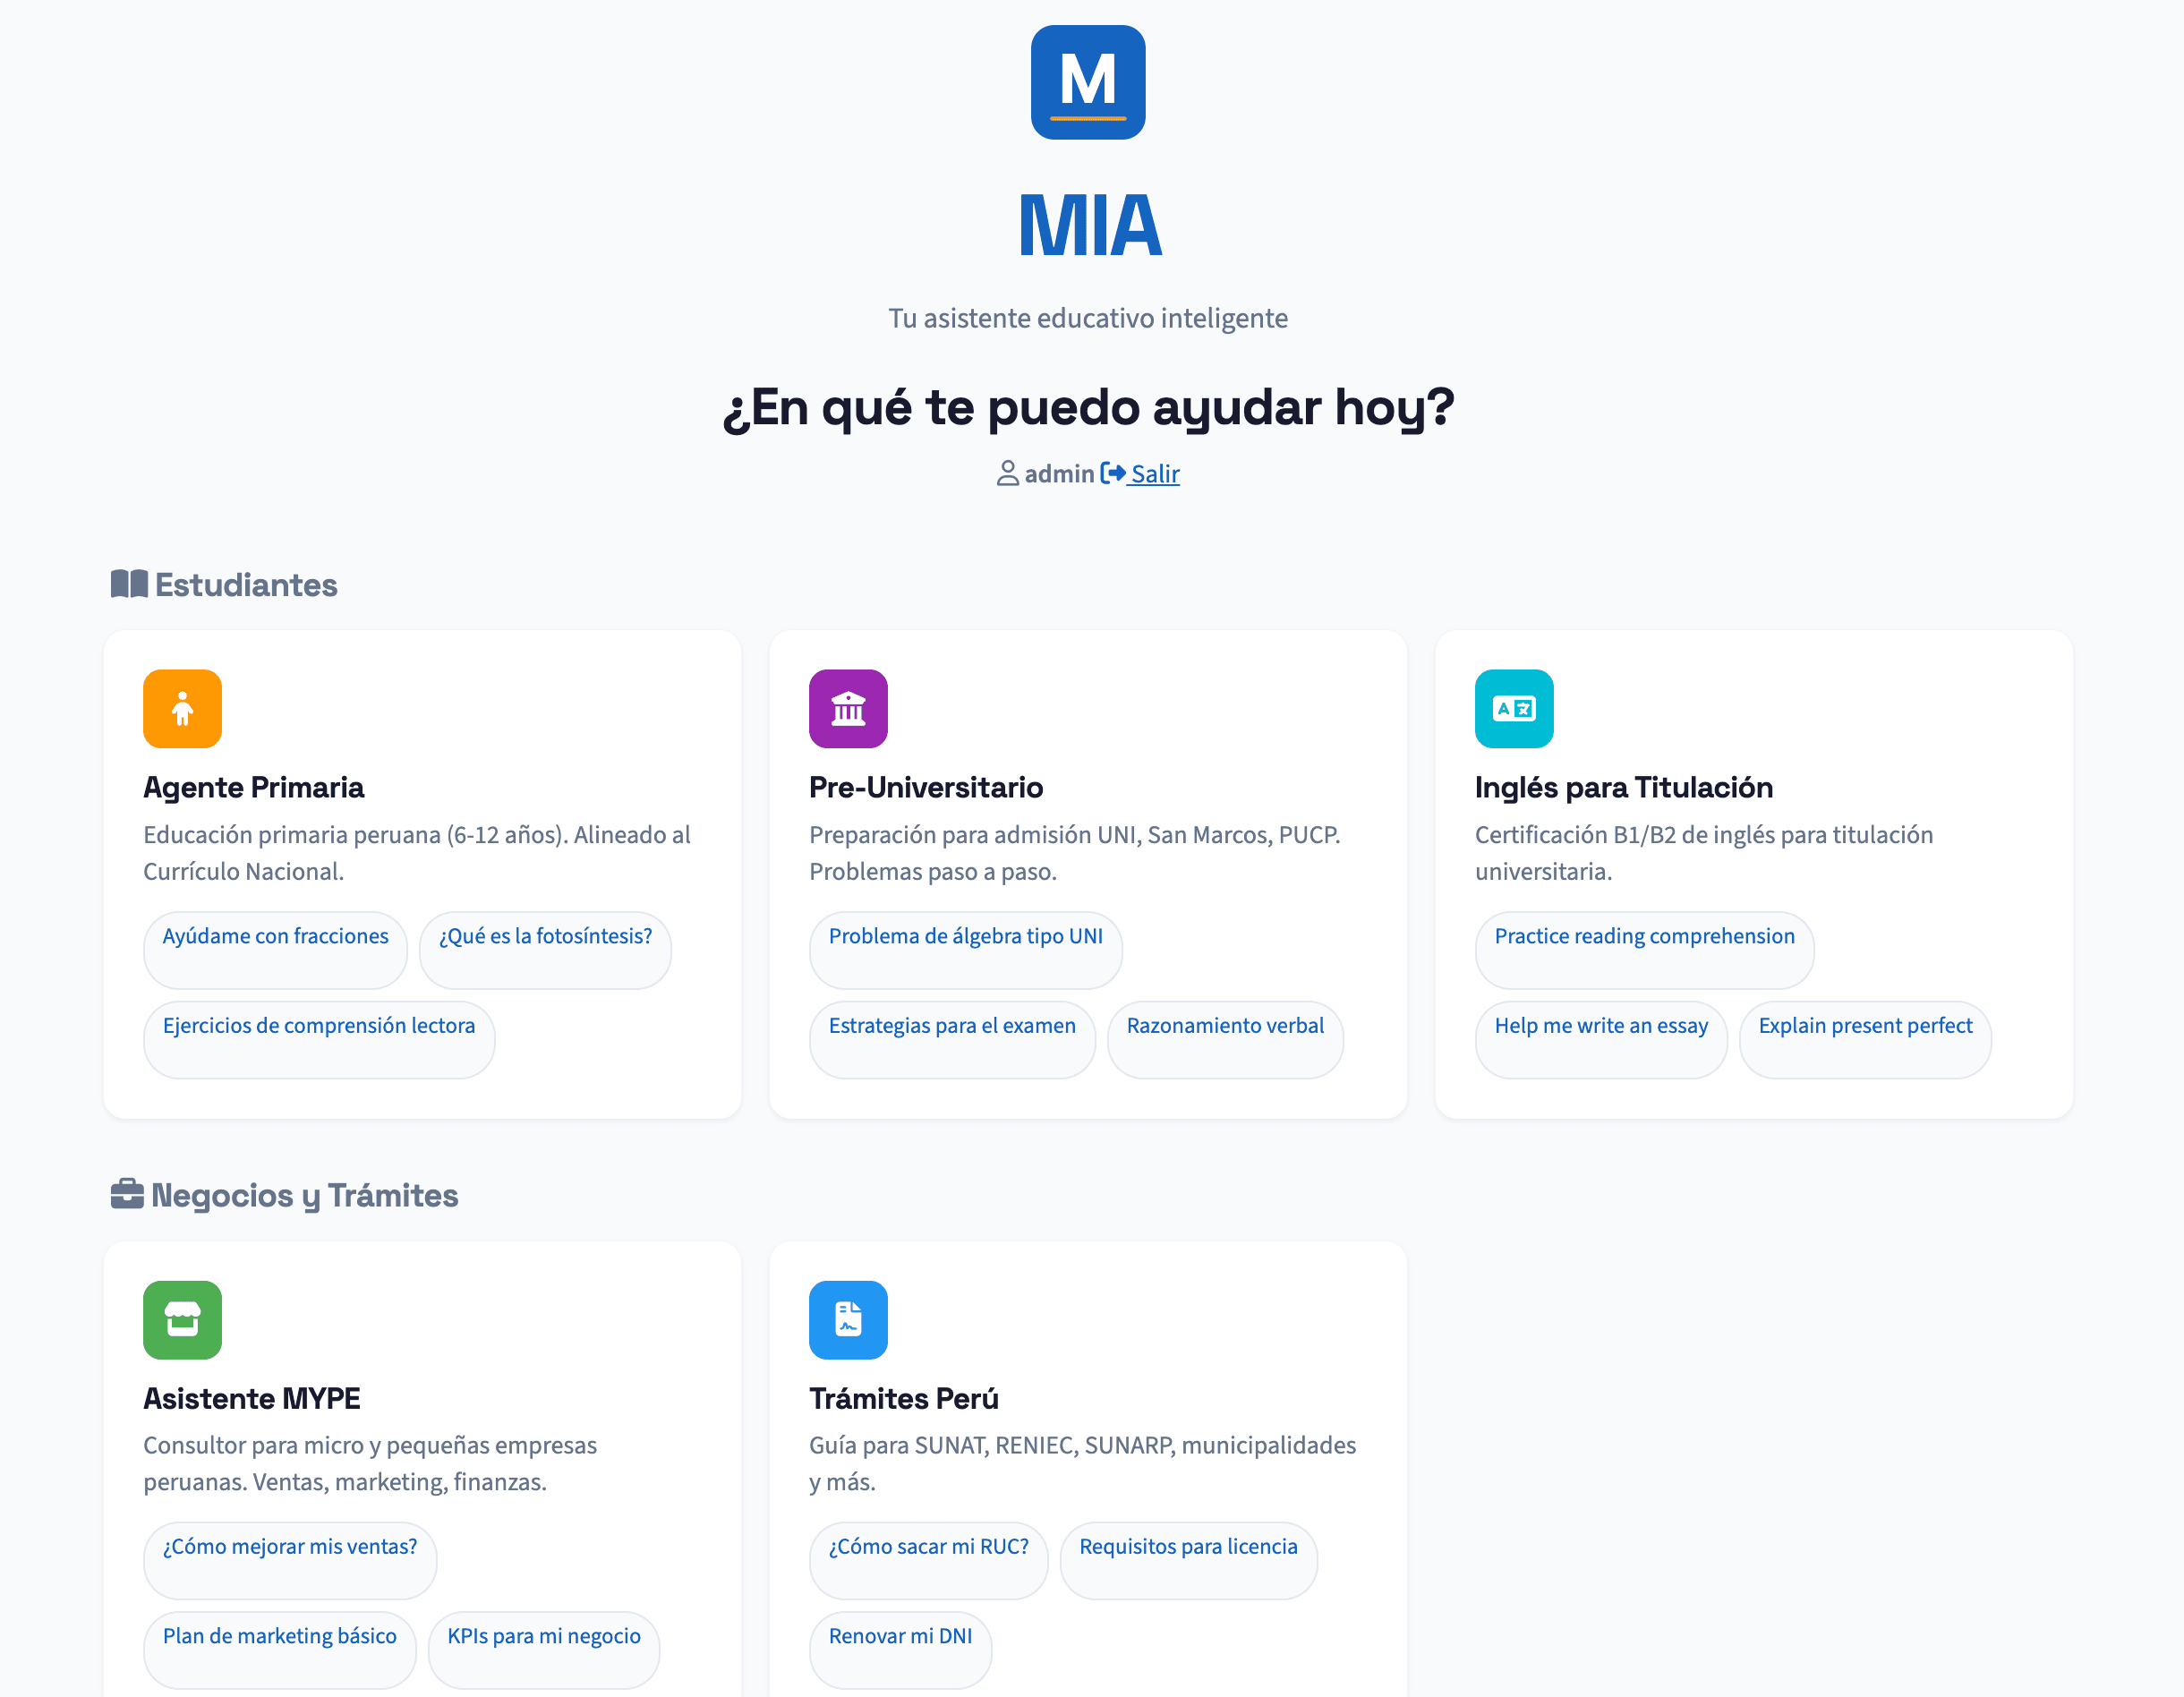
MIA v1 — R/Shiny learning assistant

R / Shiny / GenAI

R Shiny learning assistant with text, voice, image and PDF input — the app MIA was rebuilt from. Most-starred repo, MIT licensed.

R ShinyellmershinychatOpenAI GPT-4 Vision
TubeScout video discovery dashboard

TubeScout

Python

Finds high-signal YouTube videos using view-to-subscriber ratio analysis — discovery without the algorithm.

PythonStreamlitYouTube API
YouTube feed dashboard

YouTube Feed Dashboard

R / Shiny / AWS

Personal dashboard surfacing latest videos from favorite channels — AWS-hosted data pipeline, deployed on Posit Connect.

RShinyAWSYouTube API
Voice Assistant AI Streamlit interface

Voice Assistant AI

Python

Python voice assistant with speech recognition, real-time financial data and weather integration.

PythonStreamlitSpeech Recognition
roldanpack R package

roldanpack

R

Reusable analytics functions and custom visualization themes, installable via GitHub.

RPackage

Experience

Twenty years in biopharma manufacturing, from the plant floor to a global AI and data science team.

Baxter 2005–2015Baxalta 2015–2016Shire 2016–2019Takeda 2019–Present
  1. Sr. Data Engineer & Data Scientist (Sr. Manager)

    Aug 2026 – Present

    Takeda – Global

    Global AI / Data Science team (GMS) building GenAI and analytics solutions for Takeda's plasma manufacturing sites; still own AMIRA and BioTrack.

    • Moved in Aug 2026 from the LA site team into a newly formed global AI / Data Science team for Takeda's plasma manufacturing network — solutions configured per site, one engine, instead of one-site tools
    • Bring the patterns the team's multi-site solutions build on, proven on two production platforms: R computes / LLM narrates, configuration per site with one engine, the Unity Catalog data layer, usage instrumented from day one, and the 16-artifact SDLC dossier that closed a platform audit finding
    • Authored the proposal and built the proof of concept (dummy data) for a lab-investigation closure tool, the team's first project through the SDLC
    • Still own AMIRA (production, v1.10.2: per-session freshness, 322 test blocks, an evidence line under every TOMO answer) and BioTrack (production, v1.2.1 'the transparency release': one alert-rate function at ~40 call sites, 1,065 assertions, 0 failures)
    • Primary stack R/Shiny on the Databricks engine; React/Node.js where it fits
  2. Sr. Data Engineer & Data Scientist (Sr. Manager)

    Apr 2025 – Aug 2026

    Takeda Pharmaceutical

    Supported the Los Angeles Digital Roadmap, AI/ML development and advanced analytics to drive data-driven decisions.

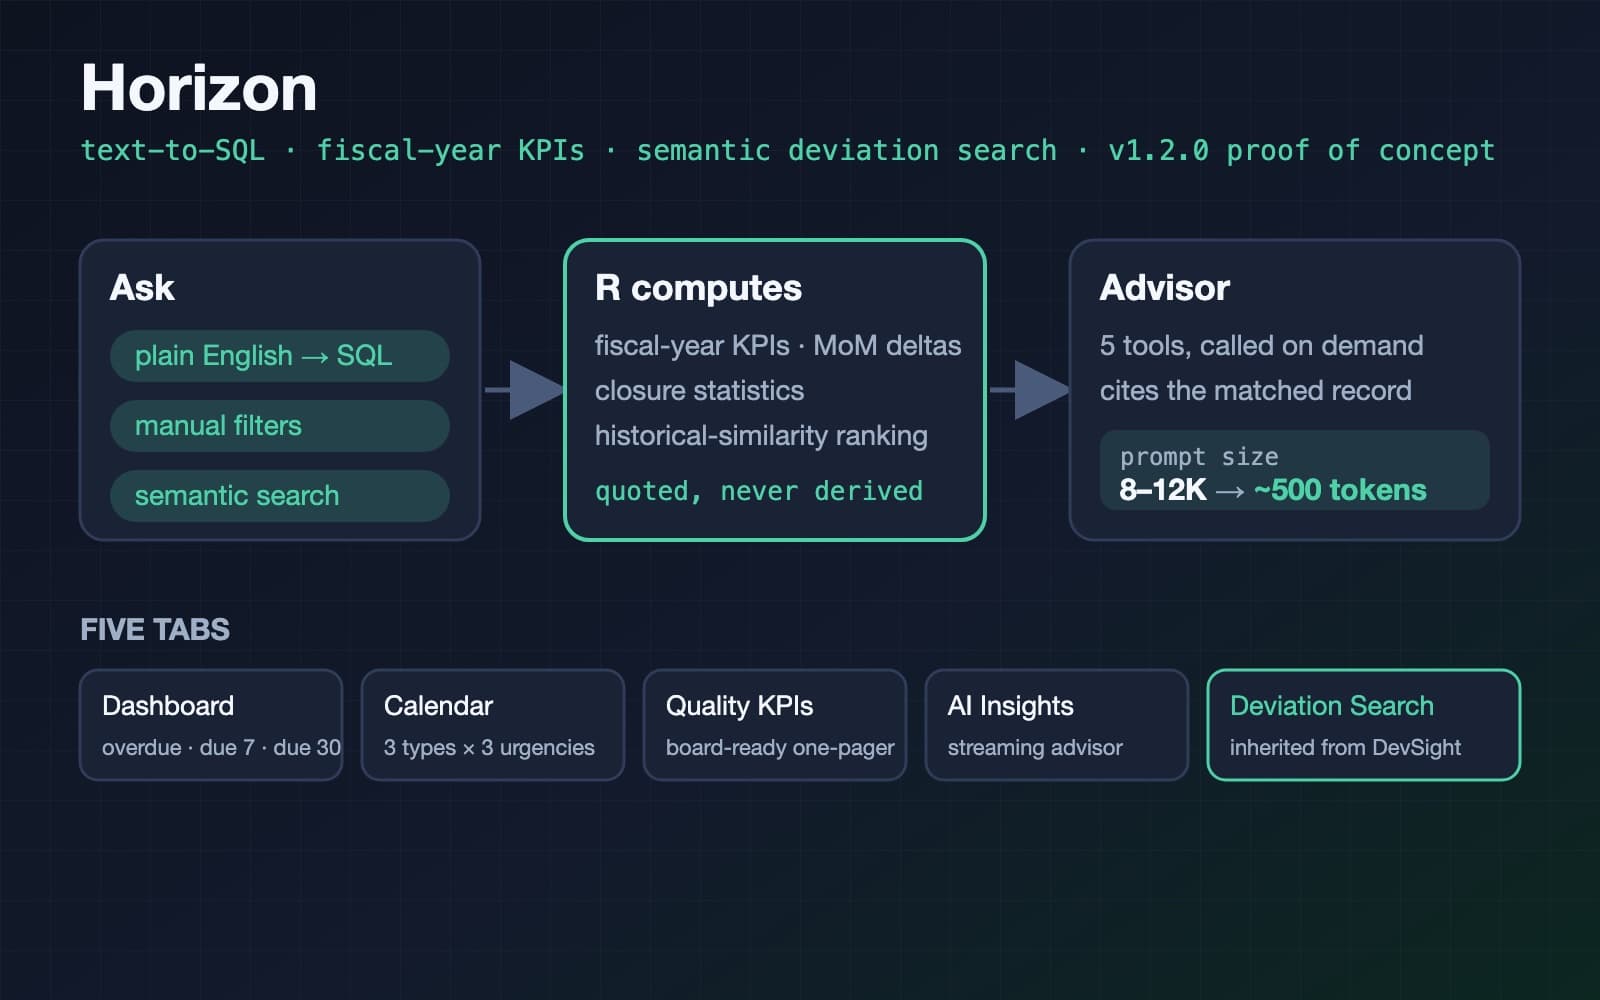
    • Owned the LA site's AI and analytics platform portfolio end to end — ETL, modeling, app, deployment: AMIRA and BioTrack in production, Horizon and LabCast as proofs of concept, plus the team's solutions portal; AMIRA and its TOMO assistant carry an initial estimate of 4,000+ hours returned through near-real-time analytics and data aggregation
    • 30+ production solutions delivered across the career; designing, building and maintaining the local data pipelines behind them
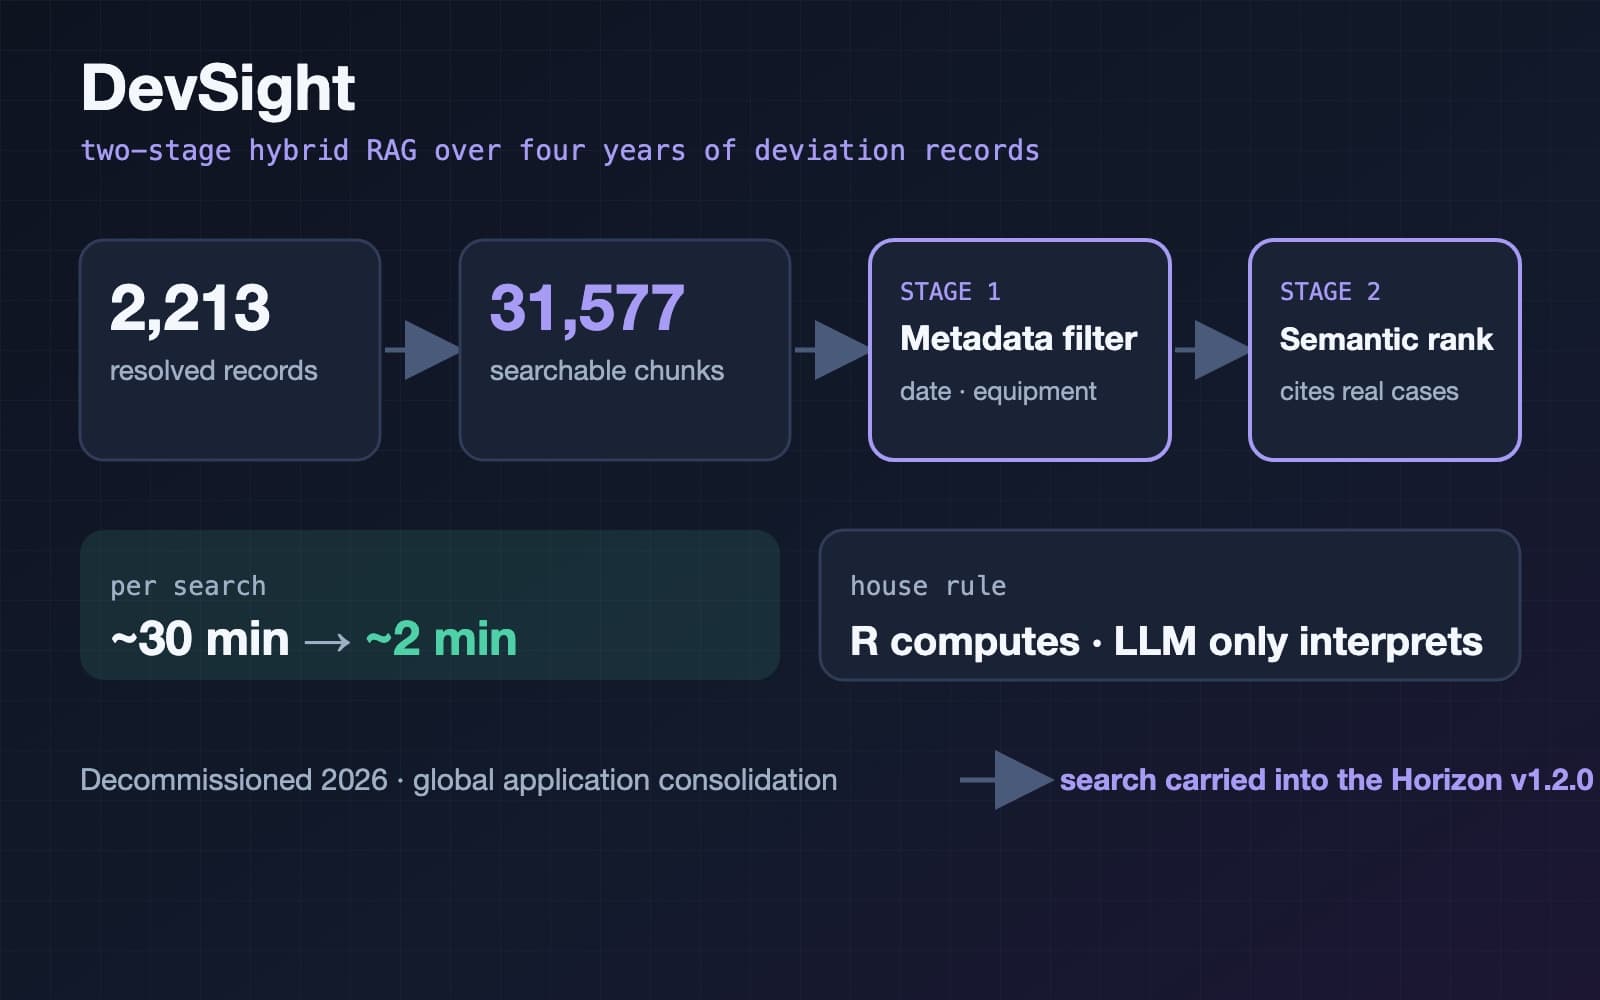
    • Anti-hallucination architecture: deterministic R computes every statistic and the LLM only interprets — ~70% fewer tokens, verified by determinism regression tests
    • DevSight: hybrid retrieval over four years of deviation records (2,213 records → 31,577 chunks), ~30 min → ~2 min per search, measured in production; carried into the Horizon proof of concept when DevSight was decommissioned in a global application consolidation
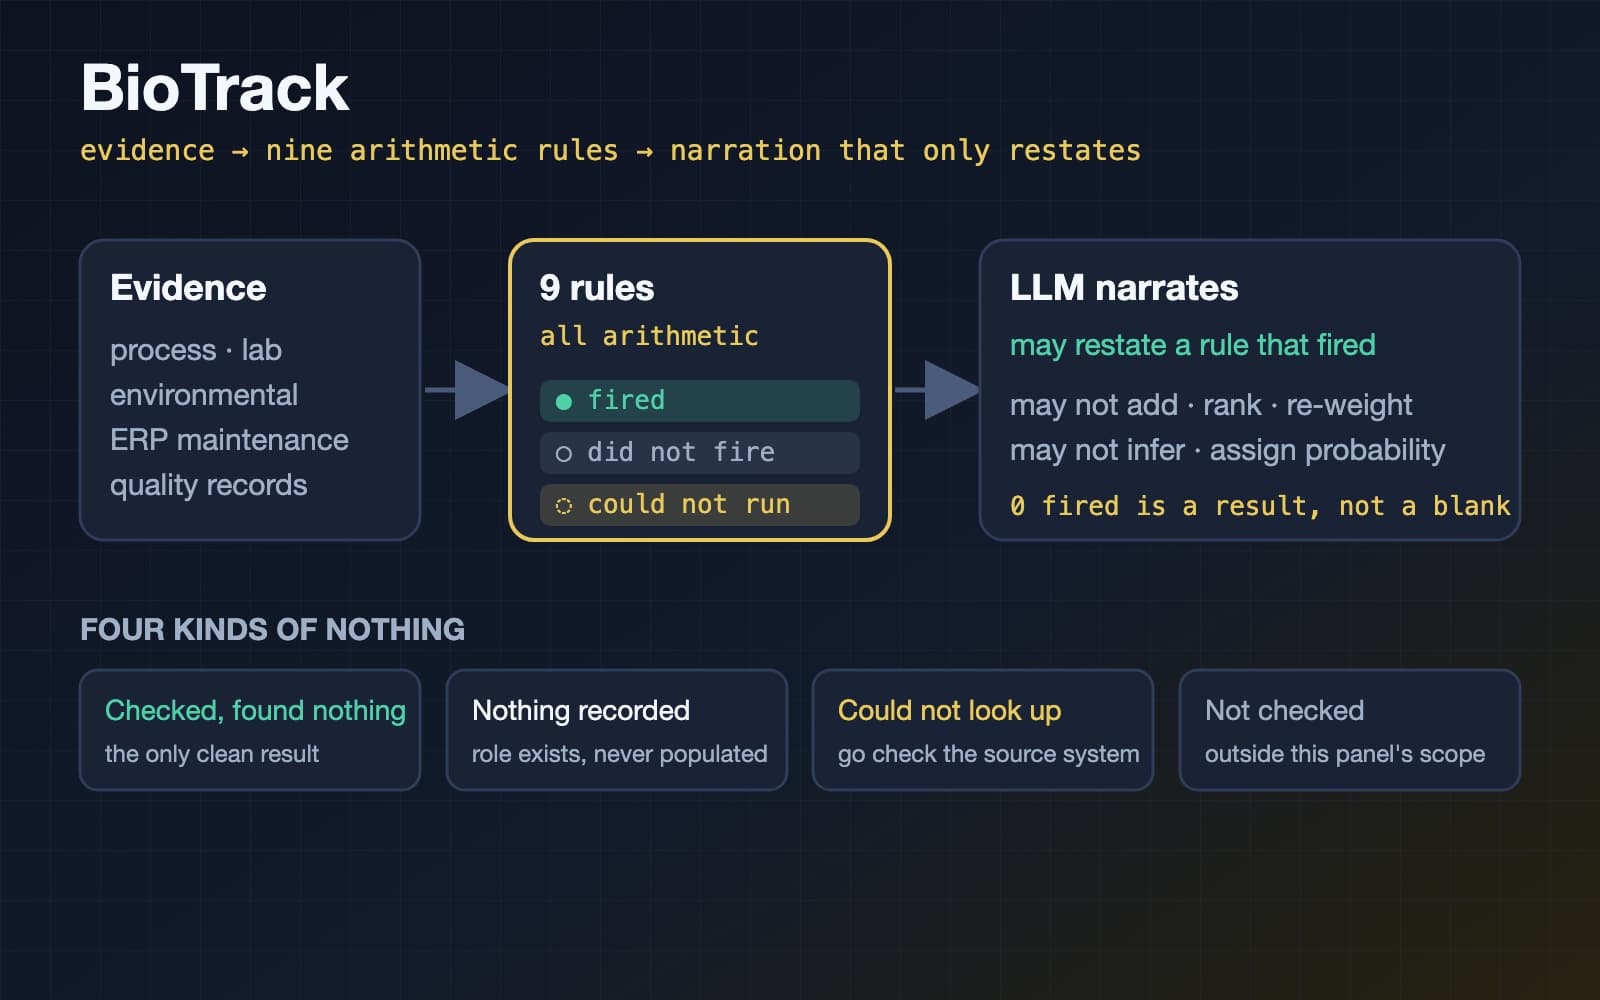
    • BioTrack, the site's manufacturing GenAI platform for microbial investigations: nine-rule deterministic hypothesis engine, ERP maintenance evidence with four kinds of 'nothing', live quality-system feed, 215-assertion regression suite; initial estimate of 450+ hours saved on data aggregation alone
    • Led the AWS S3 → Databricks Unity Catalog migration across two production platforms; authored the URS, the Architecture Council submission and a 16-artifact SDLC dossier
  3. Data Scientist III (Sr. Manager)

    Nov 2022 – Mar 2025

    Takeda Pharmaceutical

    Drove the AGILE 4.0 Digital Workstream and cutting-edge analytics to accelerate Takeda's digital capabilities across GMS sites.

    • Drove the AGILE 4.0 Digital Workstream across all GMS sites
    • Automated JD Edwards commodity deviation monitoring — 59% reduction in deviations
    • Filtration cycle-time investigation: multivariate analytics (Elastic Net, Random Forest, Boruta, SHAP) surfaced the hold-condition drivers a year of univariate work had missed as probable root causes — supported a ~25% cycle-time reduction
    • Executed local and global GMS/GQ big-data and analytics strategy
    • Built and maintained data pipelines and BI applications across all GMS plasma sites

Skills and education

What I would be interviewed on, not everything I have touched.

Languages

RPythonSQLTypeScriptJavaScriptHTML / CSS.NETJava

R Ecosystem

Shinybslib / bs4DashellmerquerychatQuarto / R Markdowntestthatpool / DBIreticulate

Data & ML

SPC (XmR, p-charts, Cpk)Elastic Net · Random Forest · XGBoostSHAP / BorutaSIMCA / OPLSWilson intervalsBase-rate analysisMultiple-comparison correctionProphet / changepointApache SparkPlotlyDashMinitabJMP

Web & Frontend

ReactNext.jsTailwind CSSNode.jsViteExpressZodPrismashadcn/uiAuth.jsSupabase (RLS)

Databases

PostgreSQLSQL ServerOracleSupabaseNeon

Cloud & DevOps

AWSDatabricksDatabricks Unity CatalogDatabricks Vector SearchDatabricks AppsPosit ConnectVercelDockerGitGitHub ActionsVitest / Playwright

BI Tools

Qlik SensePower BITableau

AI & GenAI

Anti-hallucination architectureLLM IntegrationRAG ArchitectureVector SearchTool CallingPrompt EngineeringText-to-SQLAgentic AIMultimodal / visionSSE streamingDatabricks Foundation ModelsClaude / GPT APIsOpenAI / Anthropic / OllamaVercel AI SDKVoice AI (TTS/STT)

Methodologies

Six SigmaSCRUM / AgileDMAICMLOpsProject ManagementSDLC governance (URS, non-GxP informational)WCAG 2.1 AA

Education & Certifications

  • 2026

    Build Data Pipelines with Lakeflow Spark Declarative Pipelines — Databricks Academy

  • 2026

    Data Warehousing with Databricks — Databricks Academy

  • 2026

    Building Single-Agent Applications on Databricks — Databricks Academy

  • 2023

    Oxford Machine Learning Summer School — AI for Global Goals

  • 2023

    ODSC AI Bootcamp — Open Data Science Conference

  • 2020

    Data Science Professional — HarvardX (Harvard Online)

  • 2020

    Statistical Learning, Inference & Modeling — HarvardX / Stanford Online

  • 2012

    B.S., Computer Science — Cal State Northridge

  • 2004

    Ingeniero Informático, Informatics — Pontificia Universidad Católica del Perú

Get in touch

Hiring for a staff or lead data role, or need help with a regulated analytics or GenAI system? Email is fastest.

Have a project or role in mind?

I'm open to conversations about data engineering, applied ML and GenAI in regulated and manufacturing environments. Write directly, or use the form and I'll reply from my inbox.

alexis.m.roldan.ds@gmail.com

Lancaster, CA, Pacific time